Take supplier data in and fill in the missing context
Excel, CSV, portals or existing data sources are processed. From the product information and identifiers already there, FlowCraftDB fills in the missing context from suitable sources.
20 minutes, your real supplier data, an honest assessment.
Sell new assortments sooner instead of leaving revenue stuck in your product data.
Save that much manual data work and handle far more assortment with the same team.
The error rate in prices, attributes and descriptions drops before wrong product data ever goes live.
A new supplier should be good news. In reality, what arrives first is a file with different columns, missing mandatory fields, new categories and attributes that nobody needs in the shape they were delivered.
The supplier sends their logic, you get to deal with it - with every single file.
Sales could get going, but incomplete product data blocks the go-live.
Compare the changes, correct them and move them cleanly into your systems again.
The effort grows with the assortment until only extra headcount helps.
The actual work happens before that: understanding supplier data, unifying it, filling the gaps and bringing it onto your structure.
What is manageable with a handful of suppliers quickly turns into permanent handwork at scale.
What costs days or weeks of product data work today runs as an automated process overnight.
Excel, CSV, portals or existing data sources are processed. From the product information and identifiers already there, FlowCraftDB fills in the missing context from suitable sources.
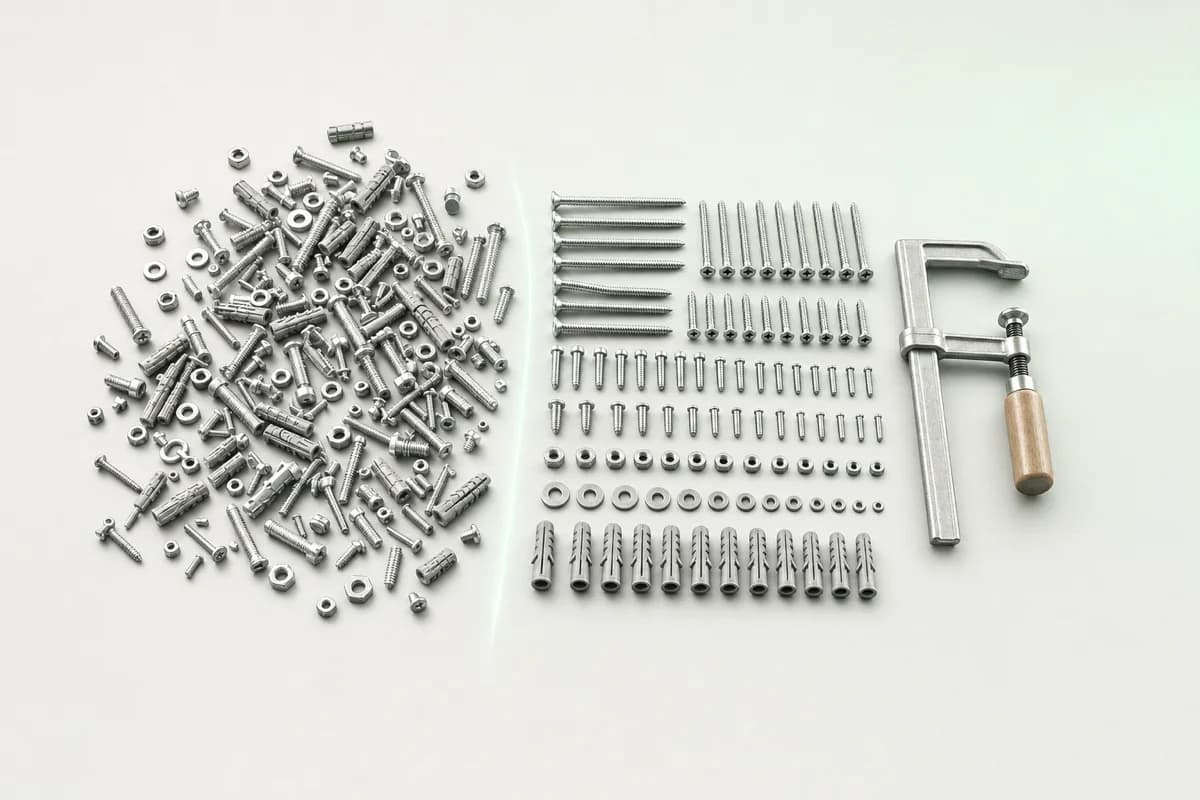
Spellings, units and formats are brought onto one standard. Values from free text and other sources are mapped to the right attributes.
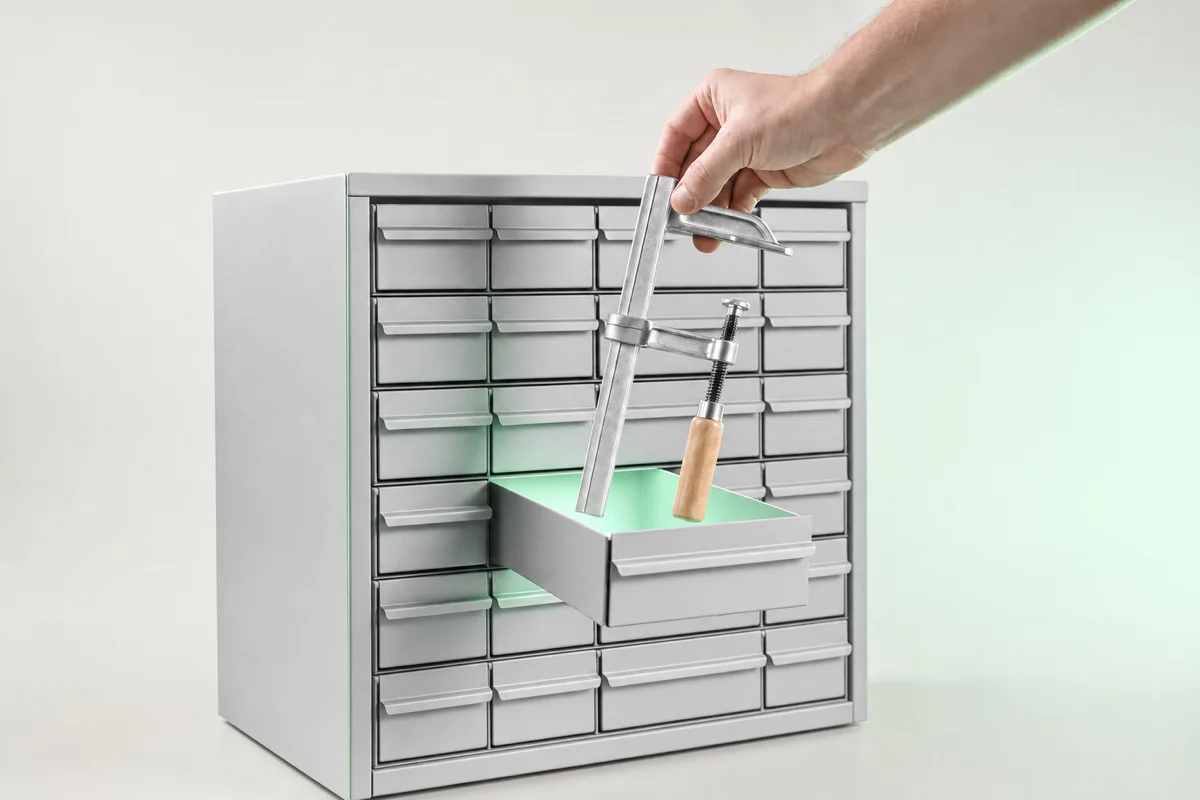
The AI reads the product context that is there and recognises which product type an article belongs to. Individual details become one unambiguous context for everything that follows.
Every value is held against its source before the finished record reaches your systems.
You define once what a sellable product record has to look like in your world. From then on, new supplier data is processed against exactly that structure, instead of your team having to understand and rebuild every new format by hand.
The 3-part aluminium combination ladder works as a step ladder with an extension section and as a leaning ladder. It complies with EN 131.
In future your team no longer adapts to every supplier.The supplier data adapts to you.
 Shopware
 Shopify
 Magento
 WooCommerce
 OXID eSales
 JTL
 PlentyONE
 Odoo
 SAP
 Amazon
 eBay
 OTTO
 Kaufland
 Conrad
 Google Merchant Center
 ChatGPT
 Google Gemini
FlowCraftDB uses AI without trusting it blindly on product data. The AI recognises product context, classification and relevant attributes, but it does not therefore treat every value as correct.
Unambiguous data is processed further. Uncertain, conflicting or unverifiable values stay visible, so your team only has to step in where a decision is genuinely needed.
Better empty than plausible but wrong.
Whether it is your own category structure, ETIM or ECLASS: for every product the matching class has to be found first. ECLASS alone offers over 40,000 classes to choose from. Then come the matching attributes and the mapping of the product information.
FlowCraftDB handles these steps automatically and files every piece of information where it belongs with you.
Understand the product
start over with the next product
Recognise the product
process thousands of products within hours on the same principle
Every day a purchased assortment cannot be sold because of unfinished product data leaves thousands of euros on the table. Once that blockade is gone, your products can finally sell and your sales team no longer has to wait for “the data to be ready”.
Four stages, two booths, one topic: how product data has to be structured for AI in retail to hold up. Come and find us on site.
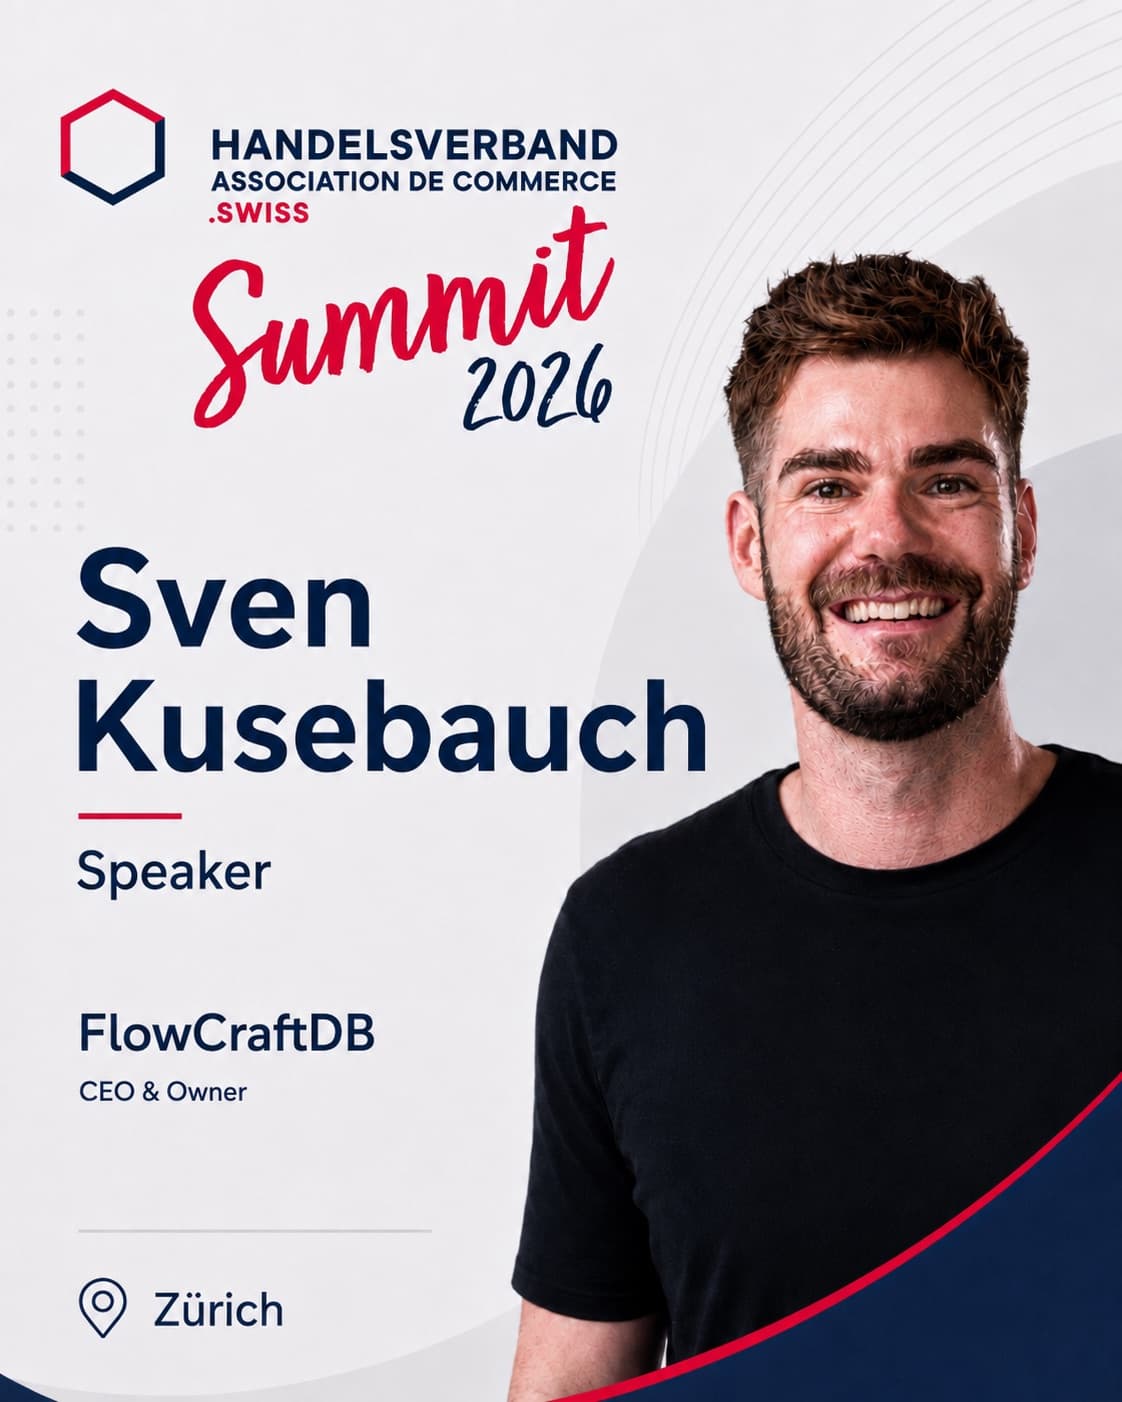
HANDELSVERBAND.swiss Summit 2026
The bottleneck is not the systems, it is the product data. The talk lays out the structural principles that make large assortments manageable - and why clean classification and binding attribute systems decide whether you can scale.
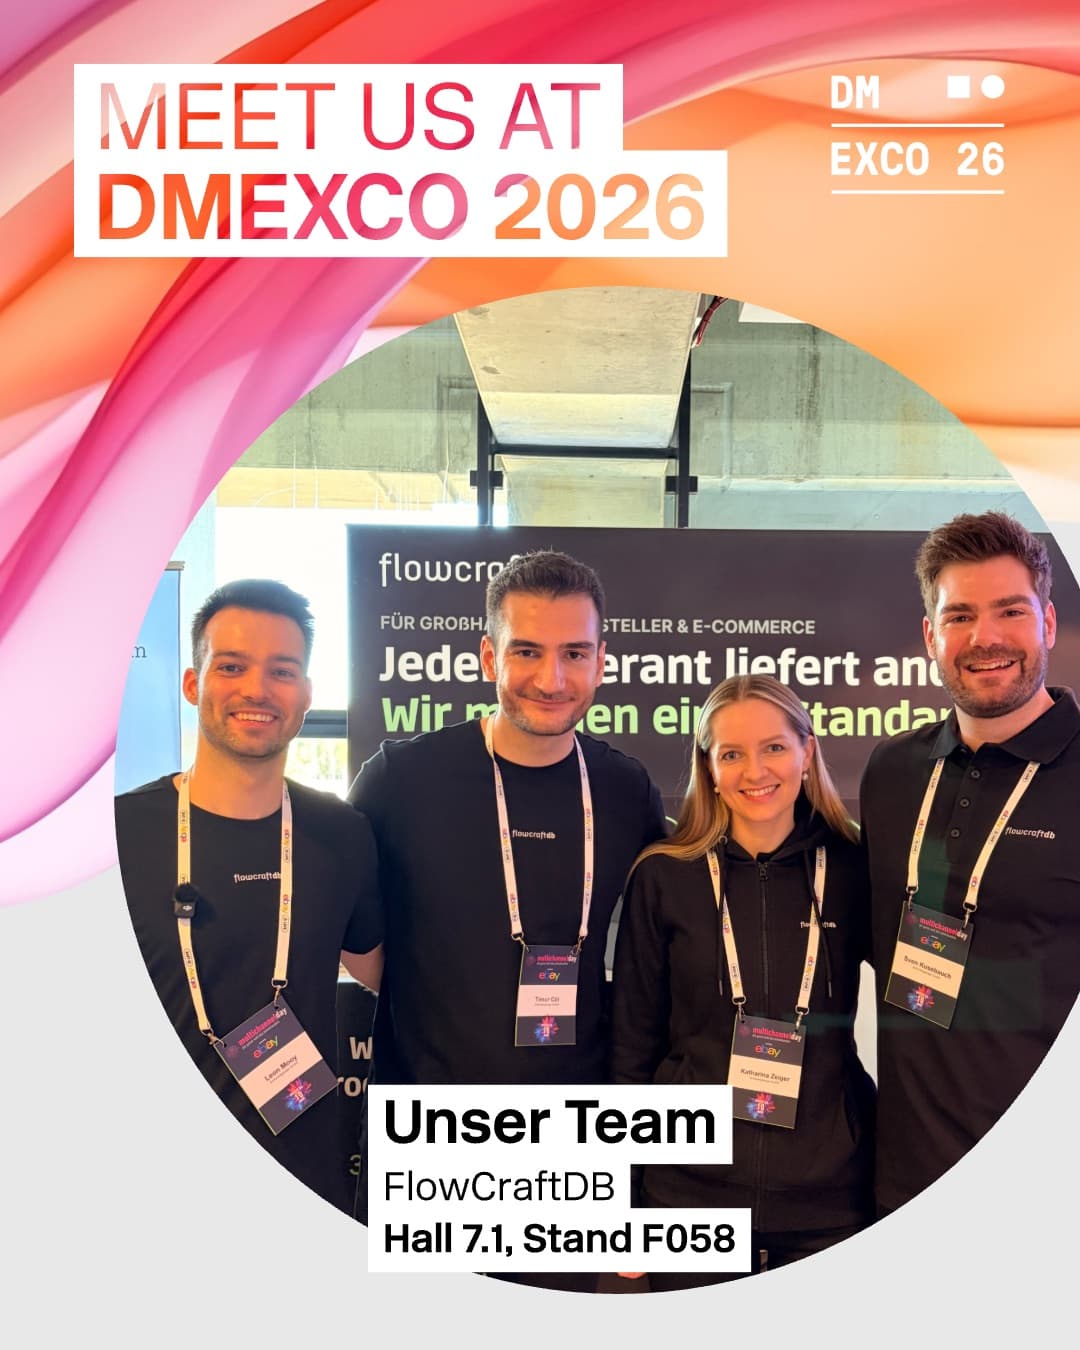
DMEXCO 2026
Two days in hall 7.1: a short conversation about how your supplier data comes in today and where it gets stuck - formats, ETIM or ECLASS classification, manual effort. We will tell you honestly whether and how FlowCraftDB can help.
DMEXCO 2026
Ten minutes on day one: how supplier data from Excel files, feeds, PDFs and portals becomes one consistent product data flow - mapped to your standard, classified against your own categories, ETIM or ECLASS.
DMEXCO 2026
Day two, same topic as in Zurich, as a masterclass: how heterogeneous supplier data becomes a reliable product data architecture - with a clear target standard, binding attribute systems and clean classification.
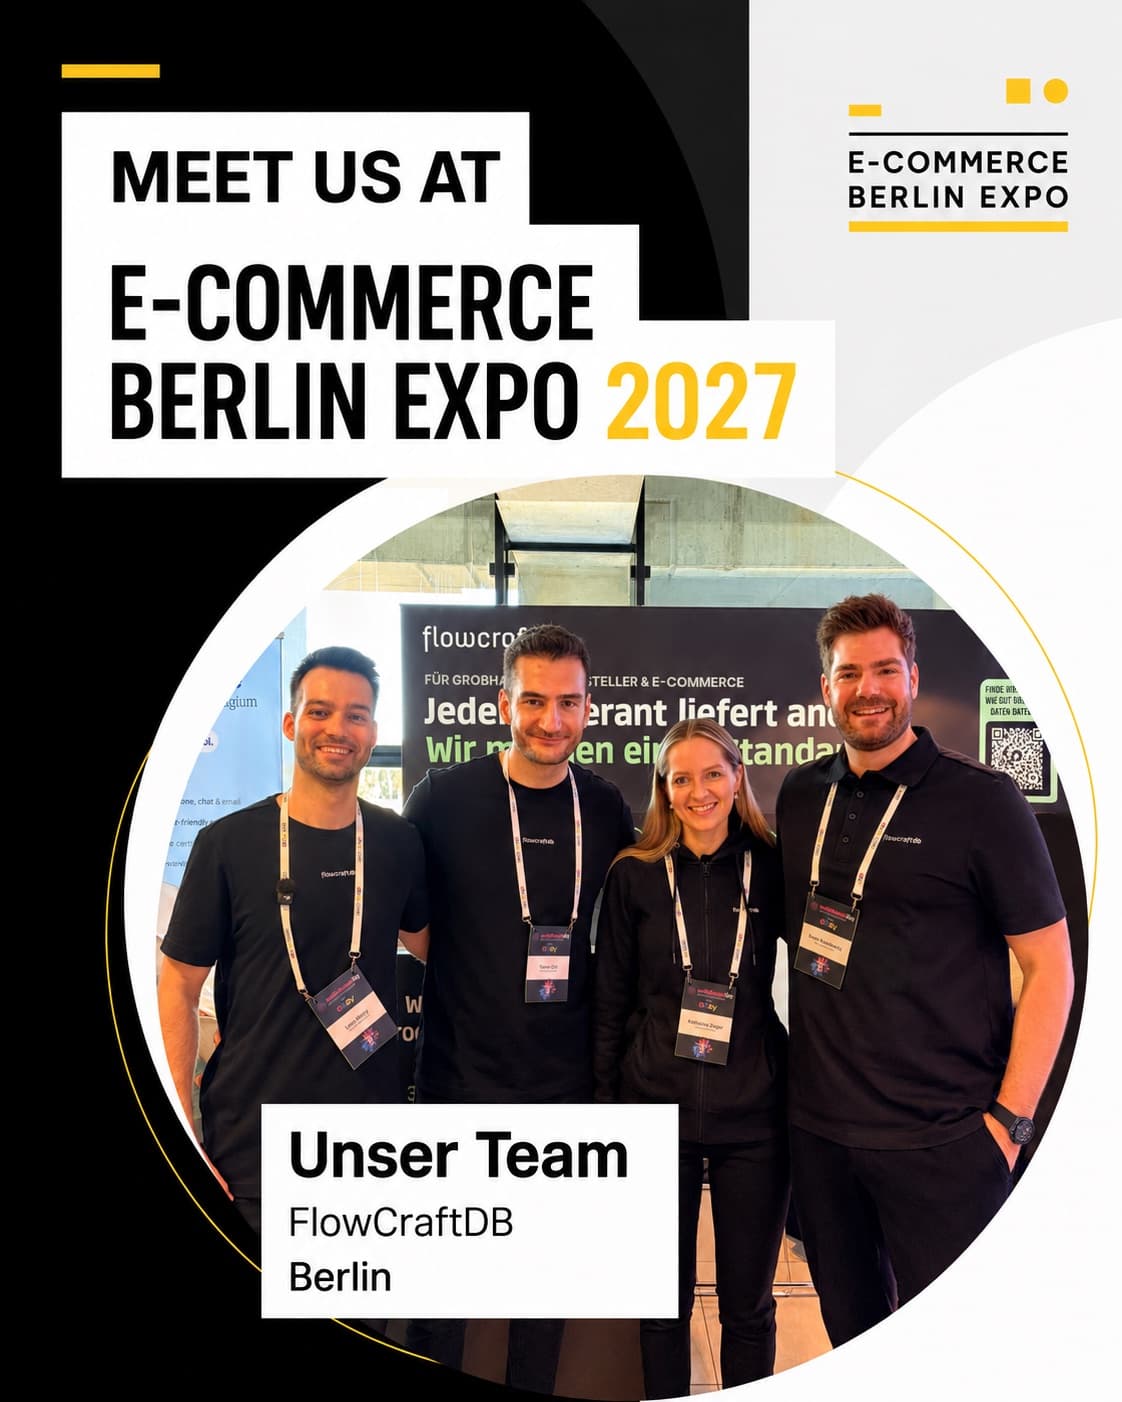
E-commerce Berlin Expo 2027
Two days in Berlin: tell us where your supplier data gets stuck - formats, ETIM or ECLASS classification, manual effort. We will tell you honestly whether and how FlowCraftDB can help. Booth number and hall follow once they are confirmed.
E-commerce Berlin Expo 2027
Berlin comes back to the foundation: why product data architecture and clean classification decide whether AI in retail holds up. Stage, day and time follow once the programme is final.
Using your own product data you'll see how FlowCraftDB handles your structures, attributes and edge cases - and where the biggest leverage sits for you.
Get in touch
We'll look together at where your biggest leverage is - using one of your real supplier files or portals. No generic sales demo.
FlowCraftDB
Frankfurter Landstraße 28
61231 Bad Nauheim
Phone
(+49) 6032 7853907
hello@flowcraftdb.de


